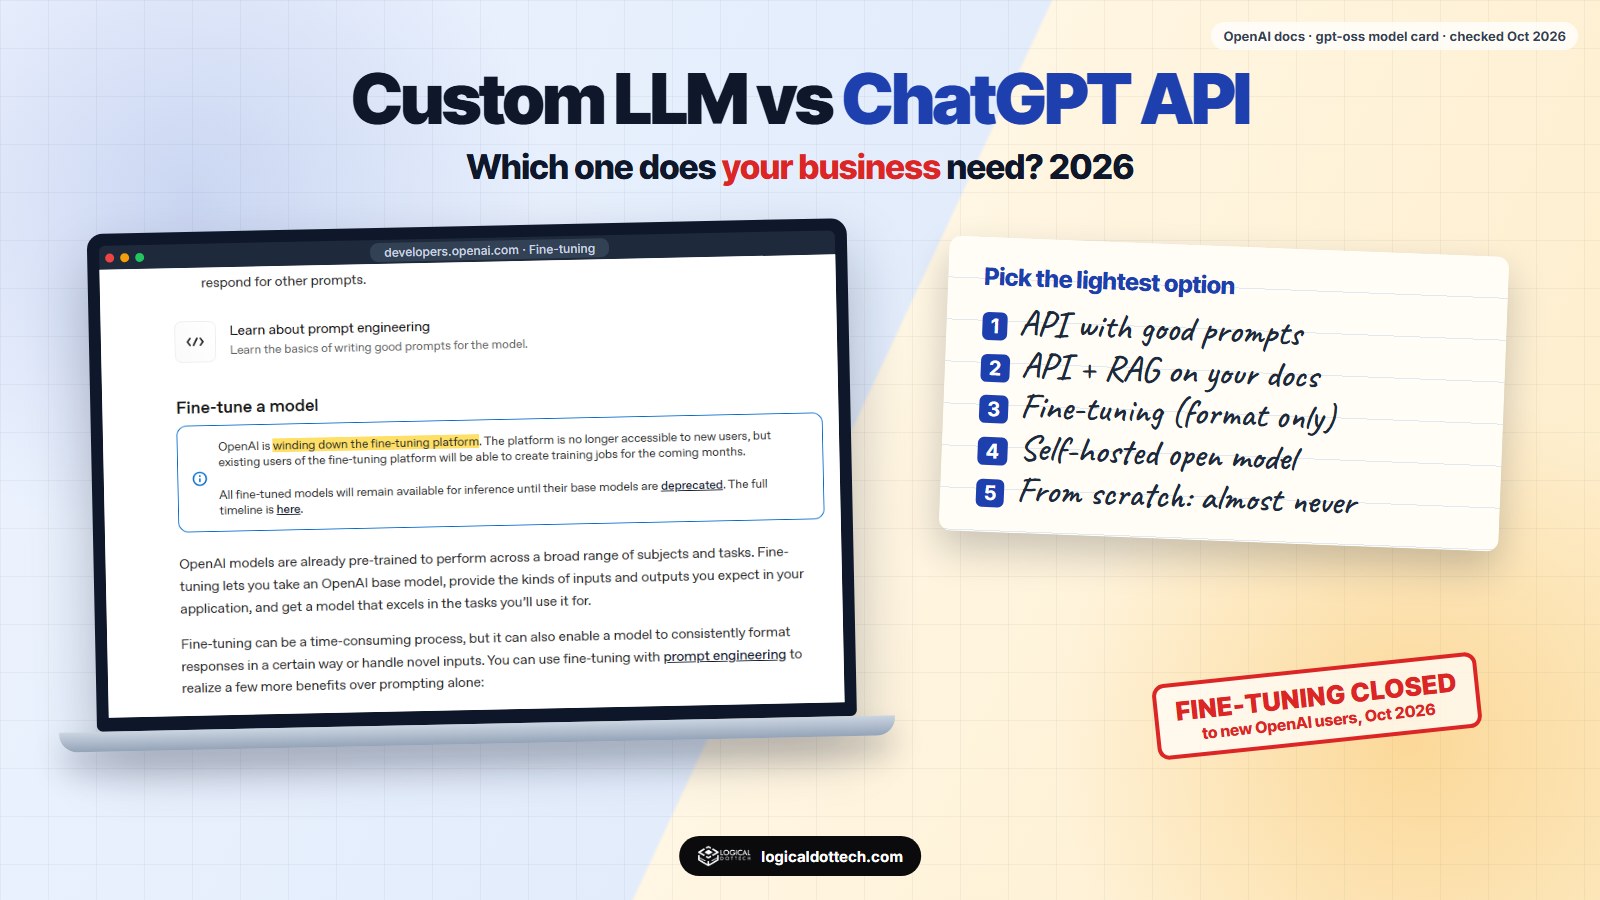
Short answer: most businesses do not need their own LLM. Start with an existing model through its API, and connect it to your own documents with RAG so it answers from your data. Fine-tune only to fix tone or output format, and note that OpenAI is winding down its fine-tuning platform for new users. Run an open-weight model on your own servers only when data must never leave them. Training a model from scratch is for very large companies.
“Custom LLM” can mean five very different things, with very different costs. This guide puts them side by side so you can tell which one a project really needs before you pay for it. The facts come from OpenAI’s own documentation and the gpt-oss model card, checked on 19 October 2026.
The five options at a glance
| Option | What it means | Good for | Effort |
|---|---|---|---|
| 1. API with good prompts | Use ChatGPT, Claude or Gemini models through their API with instructions you write | Drafting, summaries, classifying messages | Days |
| 2. API plus RAG | The model answers from your own documents, found at question time | Support bots, internal knowledge, product questions | Weeks |
| 3. Fine-tuning | Train an existing model further on your examples | A fixed output format, a narrow task, a house style | Weeks, plus good example data |
| 4. Self-hosted open-weight model | Download a model such as gpt-oss and run it on your own servers | Data that must never leave your systems | Weeks to months, plus servers to run |
| 5. Training from scratch | Build a new model on your own huge dataset | Very large companies and research labs | Months to years, very high cost |
When a vendor says “custom LLM”, ask which of these five they mean. Most good business projects are option 2.
Option 1: Is the API safe for business data?
This is usually the first worry. OpenAI’s data controls page says that since 1 March 2023, data sent to the API is not used to train or improve its models unless you opt in.
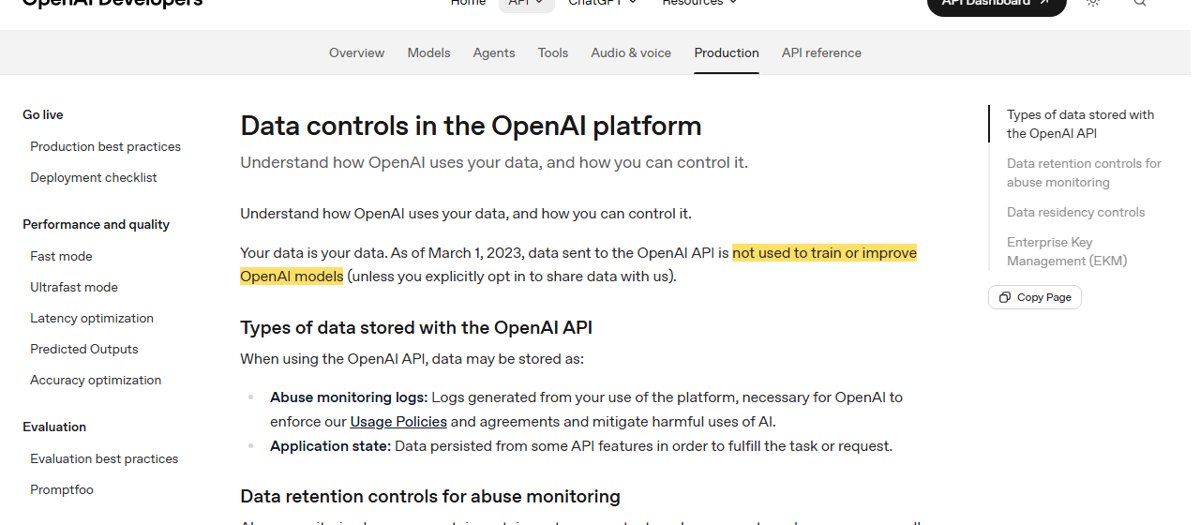
Three more details from the same page matter for a business:
- Abuse monitoring. Logs may be kept for up to 30 days, unless the law requires longer.
- Zero data retention. Available, but only to customers OpenAI approves.
- Data residency. Eligible customers can choose where data is stored, including India, the US, Europe, the UK, Canada and Australia. Processing in-region is listed only for the US, Europe and the UAE.
If you handle personal data of people in India, the Digital Personal Data Protection Act, 2023 applies to how you collect and use it, whichever model you choose. Read the terms of any provider before you send customer data, and send only what the task needs.
Option 2: What is RAG, and why does it fit most businesses?
RAG (retrieval-augmented generation) keeps the model as it is and gives it the right part of your documents with each question. A customer asks “what is your return policy for sale items?”, your system finds the matching paragraph in your policy, and the model answers from that paragraph.
- Collect the documents. Policies, product sheets, past support answers, manuals.
- Clean them. Remove old versions and contradictions. The assistant can only be as right as its sources.
- Index them for search. Split them into short sections and store them so the closest matches can be found fast.
- Answer with sources. Pass the best matches to the model with the question, and show the customer which document the answer came from.
- Test with real questions. Use 50 to 100 questions customers really asked, and check every answer before launch.
Why it fits: when a policy changes, you update the document, not the model. And because answers point to a source, your team can check them.
Option 3: When is fine-tuning worth it?
Fine-tuning trains an existing model further on your examples. OpenAI says it helps with things like a consistent output format, classification, and shorter prompts that cut cost and delay. It also says “the prompt engineering process may be all you need”. Fine-tuning teaches style and format well. It is a poor way to teach facts that change, which is what RAG is for.
There is a bigger change to plan around. OpenAI’s fine-tuning guide now opens with this notice:
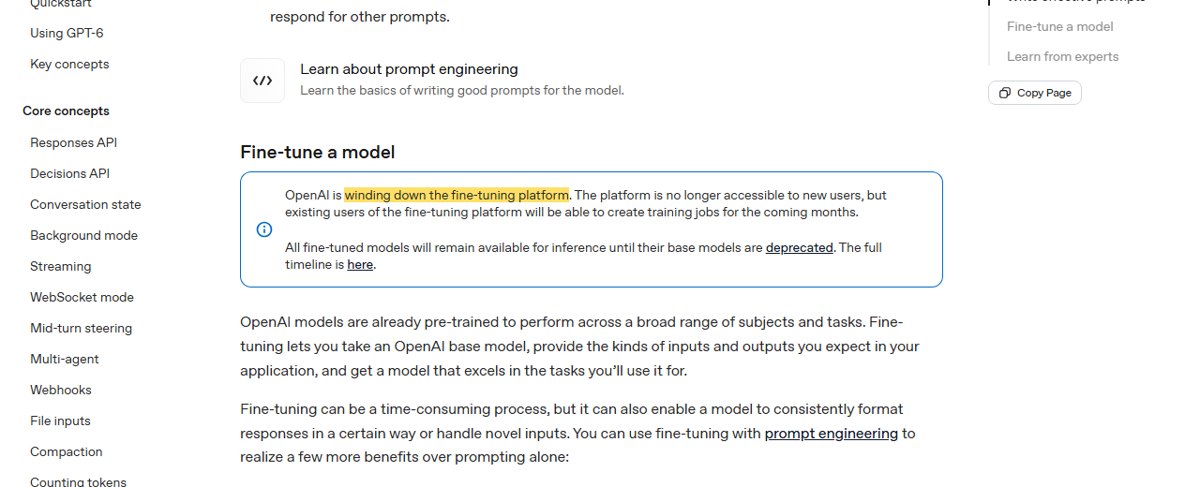
New users can no longer use OpenAI’s fine-tuning platform. Existing users can still create training jobs for the coming months, and fine-tuned models keep working until their base models are deprecated. If a proposal you receive is built on fine-tuning an OpenAI model, ask how it will work after that. Fine-tuning open-weight models on your own or rented servers is still possible.
Option 4: When should you host your own model?
When the data must stay inside your own systems, for example in some healthcare, legal, finance or government work, or when a contract forbids sending data to an outside provider. Open-weight models make this practical. OpenAI’s gpt-oss models are released under the Apache 2.0 licence:
| Model | Size | Hardware, per the model card |
|---|---|---|
| gpt-oss-120b | 117B parameters, 5.1B active | Fits on a single 80GB GPU, such as an NVIDIA H100 or AMD MI300X |
| gpt-oss-20b | 21B parameters, 3.6B active | Can run within 16GB of memory |
The trade-off is that you now run the servers: security updates, uptime, scaling when traffic grows, and testing each new model version. You still need RAG on top if the model has to answer from your documents.
Option 5: Should you train a model from scratch?
Almost certainly not. Training a new model takes a very large dataset, specialist staff and a lot of computing power, and for most business tasks it would still do worse than the models you can rent or download today. If someone proposes it for a small or mid-size business, ask what option 2 or 4 cannot do for you.
Five questions that decide it
- Must the data stay on your servers? Yes means option 4. No means start with option 1 or 2.
- Does it need to answer from your own documents? Yes means RAG.
- Do the facts change often? Yes means RAG, not fine-tuning.
- Is the problem tone or format, not facts? Better prompts first, fine-tuning only if prompts fail.
- Who will look after it? A self-hosted model needs someone to run it every month after launch.
Common mistakes
| Mistake | What to do instead |
|---|---|
| Fine-tuning to teach the model your prices or policies | Put them in documents and use RAG, so updates take minutes |
| Building on a platform that is closing to new users | Check the provider’s current docs before you plan |
| Feeding old and new versions of the same policy | Clean the documents first |
| Launching without testing real questions | Test 50 to 100 real customer questions and check every answer |
| No sources shown with answers | Show which document each answer came from |
If you want help choosing or building, our custom AI and LLM development service starts with a short scoping call to work out which of the five options you need, then builds a first version that answers one real set of questions well. See also our AI development services. We work with clients in India, the US, Canada, the UK and Australia. Book a free 30-minute call.
Common questions
Does my business need its own LLM?
Usually not. Most business needs, such as a support assistant, a sales helper or a tool that answers from your own documents, are met by an existing model through its API plus your data fed in at question time (RAG). Your own hosted model makes sense mainly when data must never leave your servers.
Does OpenAI train on data sent through the API?
No, not by default. OpenAI’s data controls page says that since 1 March 2023, data sent to the API is not used to train or improve its models unless you opt in. Abuse monitoring logs may be kept for up to 30 days, and zero data retention is available to approved customers.
What is RAG?
RAG (retrieval-augmented generation) means that when someone asks a question, your system first finds the relevant parts of your own documents and passes them to the model with the question. The model answers from your content without being retrained, and you can update the documents any time.
Can I still fine-tune OpenAI models?
Only if you were already using the platform. OpenAI says it is winding down fine-tuning: new users no longer have access, existing users can create training jobs for the coming months, and fine-tuned models stay available until their base models are deprecated.
Can I run a ChatGPT-like model on my own server?
Yes. Open-weight models such as OpenAI’s gpt-oss can be downloaded and run on your own hardware under the Apache 2.0 licence. The larger gpt-oss-120b fits on a single 80GB GPU, and the smaller gpt-oss-20b can run within 16GB of memory.
How much does a custom AI assistant cost?
It depends far more on the work around the model than on the model itself: cleaning your documents, building the search, connecting your systems, testing answers and maintenance. Ask for a fixed-scope first version that answers one type of question well before paying for a large build.
Sources checked on 19 October 2026: OpenAI, Data controls in the OpenAI platform, OpenAI, Fine-tuning guide and gpt-oss-120b model card on Hugging Face. AI providers change their products often, so check the current documentation before you commit to a plan.